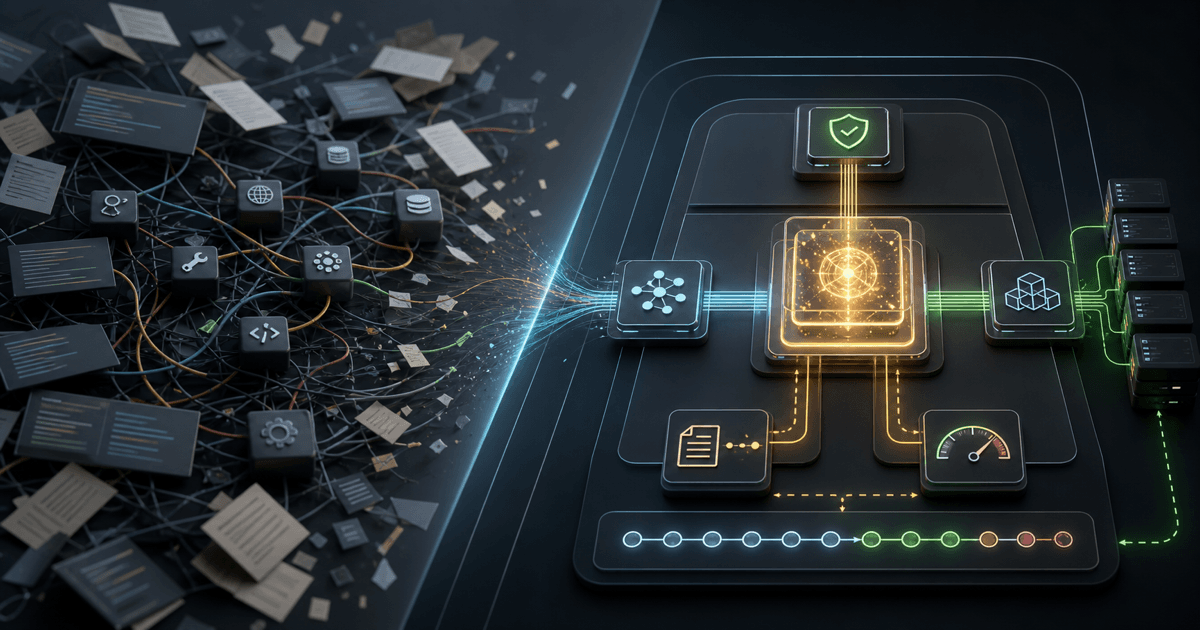
Many agentic AI systems start with a capable model, a prompt, retrieval, and a list of tools. The demo succeeds when the agent finds an answer or completes an action.
That can be a sensible starting point. The production question begins when an action changes money, customer state, regulated data, or production infrastructure: which facts and permissions made that action legitimate, and what happens when one of them is wrong?
Model quality still matters. A stronger model cannot by itself prove which context it saw, which authority it used, which policy ran, or whether a tool changed external state. Those questions require controls and records outside the prompt.
That surrounding system is the harness.
ContextOS is the portable decision-control, evidence, and conformance architecture around agentic AI runtimes. An implementation uses it to turn “LLM plus tools” into a governed system; ContextOS itself is not the hosted runtime.
Research readout
The sources below support different parts of the case. Product guides describe implementation patterns; risk frameworks identify failure modes; a benchmark tests how untrusted tool output can redirect an agent. None of them measures ContextOS outcomes. The controls in the right column are design implications, not findings from those sources.
| Source | Practical signal | What it means for production agents |
|---|---|---|
| Anthropic: Building effective agents | Start with the simplest workable design; autonomous agents can trade latency and cost for flexibility, and need stopping conditions and sandboxed testing. Anthropic notes that parts of this 2024 tooling survey have since changed. | Choose a bounded workflow first; add an autonomous loop when evaluation shows a task benefit. |
| OpenAI Agents SDK docs | The SDK provides orchestration, tools, handoffs, guardrails, and tracing for agent apps. | An application still has to define its own evidence, authority, and release contract across the runs it operates. |
| OpenAI guardrails and human review | Guardrails decide whether a run should continue, pause, or stop; tool-level checks matter around side effects; approvals need resumable state. | Safety belongs at input, output, tool, and approval boundaries, not only in a system prompt. |
| LangSmith observability docs | Traces capture model and tool calls and help inspect execution. | A trace needs declared links to policy, evidence, and a decision record before it can support governed audit or replay. |
| NIST AI RMF Core | The Govern, Map, Measure, and Manage functions frame organizational AI risk work. | Runtime records can supply evidence for that work; a harness alone does not satisfy an organization’s risk-management obligations. |
| OWASP Top 10 for Agentic Applications 2026 and OWASP LLM Top 10 2026 | Tool misuse, identity and privilege abuse, memory poisoning, and cascading failures are named risks. The 2026 LLM edition incorporates incident evidence. | Test tool and identity boundaries as enforceable controls, rather than treating a risk list as proof of safety. |
| AgentDojo prompt-injection benchmark | Untrusted tool responses can hijack tool-using agents; the benchmark includes both legitimate tasks and adversarial security cases. It also finds ordinary task failures without attacks. | Evaluate task completion and unauthorized-action resistance separately. A denied action can be a successful security result even when the user task fails. |
Before and after matrix
Read this like a design review checklist. If the “before” cell describes your current system, the row names the production gap.
| Area | Before ContextOS: common agent stack | What breaks | After ContextOS / harness engineering | Proof a geek can inspect |
|---|---|---|---|---|
| Unit of work | A user message enters a prompt and the agent decides what to do. | There is no stable runtime object to authorize, measure, replay, or compare. | The invokeAgent envelope identifies the request; the runtime materializes RunContext with run id, tenant, user, agent, intent, safety ceiling, trace, and budget. | request_id and trace.trace_id in the request; run_id, safety_mode, and run_budget in RunContext. |
| Task boundary | ”You are a support agent” plus natural-language instructions. | Scope expands by accident. The same prompt handles refunds, fraud, shipping, retention, and escalations. | The Intent-Task Catalog maps raw requests to canonical intents and approved task templates. | Intent classification record, intent_ref, task_template_id, allowed task list. |
| Context | RAG pulls whatever looks semantically close at run time. | Stale docs, policy conflicts, tenant leakage, and silent context truncation become invisible causes of bad actions. | A Context Pack declares source priorities, buckets, budgets, policies, tools, memory, evals, and decision specs. | pack_id@version, snapshot_version, context_ledger, budget_report, evidence_manifest. |
| Planning | The model loops until it thinks it is done. | Cost spikes, repeated tool calls, hidden no-progress loops, and non-deterministic branching. | The Decision plane runs Planner -> Critic.verify -> Executor -> Critic.score -> Consolidate under budget and loop guards. | Plan transcript, critic verdicts, max_tool_calls, max_replan_attempts, loop-guard events. |
| Tool surface | Function calling exposes a broad registry because “the model can choose.” | Excessive agency: the model can discover and combine capabilities the workflow never needed. | The Tool Gateway receives only the compiled tool manifest allowed by pack, policy, tenant, and safety mode. | CompiledContext.tool_manifest, adapter ids, capability ids, approval modes, arg constraints. |
| Authority | One backend service token executes most actions. | The agent inherits more privilege than the user, the workflow, or the risk class requires. | RunContext separates user delegation from agent workload identity; tool calls exchange scoped credentials per capability. | Delegation scopes, workload identity, policy_decision_id, credential exchange audit metadata. |
| Approval | A UI asks a human to click approve before high-risk actions. | The approver may see mutable data, the pause may not be resumable, and denial handling differs per workflow. | Approval gates bind approver identity to frozen evidence and persist a resumable verdict. | Gate id, approver, evidence snapshot hash, and approval event; the resulting DecisionRecord uses DECIDED, REJECTED, or DEFERRED as appropriate. |
| Policy | Prompt says “do not refund above 5000” or a post-hoc checker reviews output. | The model can ignore policy, misunderstand policy, or comply in prose while tools still execute. | Policy bundles run outside the model at compile, plan, and execute boundaries. They produce typed decisions. | Policy bundle version, matched rule_ids[], policy_decision_id, input facts, verdict. |
| Guardrails | A classifier checks the first user message or the final answer. | Side effects happen between those two points. Tool arguments and tool results are under-checked. | Guardrails exist at input, output, tool, approval, memory, and release boundaries. | Tool guardrail results, redaction reports, must_refuse, must_escalate, evaluator verdicts. |
| Memory | The agent writes “important” facts into a vector store. | Prompt injection and stale assumptions persist across sessions; memory becomes a second ungoverned prompt. | Promotion-aware memory separates capture, candidate, review, promotion, decay, and erasure. | Memory write class, consent basis, contradiction check, classification, promotion status, trace link. |
| Observability | Logs contain prompt, response, tool call, maybe latency. | Logs show activity but not authority, policy, evidence, or replayability. | Observability emits W3C-style trace correlation plus typed runtime artifacts. | OTEL spans, trace_id, tool transcripts, scorecards, replay packet, DecisionRecord link. |
| Audit | After an incident, engineers reconstruct what happened from logs and Slack. | Audit depends on human interpretation and live systems that may have changed. | Governed decisions emit a DecisionRecord as the durable receipt. | Required evidence_refs, policy_decisions, controls, approvals, lineage, and trace; optional hash and signature under an adopted audit profile. |
| Replay | Re-run the prompt and hope the same model, docs, and tools behave similarly. | Live retrieval, model drift, policy edits, and tool state make reproduction impossible. | A ReplayPacket pins inputs and uses recorded transcripts so side-effecting tools are not called again. | Exact comparison for deterministic compiler and policy artifacts; declared property or scorecard checks for model-dependent stages. |
| Evaluation | A few golden prompts and manual review before launch. | Regressions ship through prompt edits, model upgrades, policy changes, and tool changes. | Evaluation and Observability scores Policy, Utility, Latency, Safety, and Economics on live samples and golden replays. | RunScore, golden set id, evaluator suite version, release-gate verdict. |
| Cost control | Token and tool spend are inspected after the bill arrives. | Agent loops hide cost inside “reasoning.” Expensive paths become normal. | RunBudget caps tokens, wall-clock, tool calls, replans, and cost; routing policy chooses the model profile. | Budget usage, cost per decision, router decision, and p95/p99 by intent. |
| Rollback | Revert a prompt or disable a feature flag. | The rollback may not restore the old behavior because context, tools, policy, and model route changed independently. | Rollback re-pins the prior release tuple: pack, policy, tool manifest, evaluator suite, model profile, memory snapshot rule. | Release tuple, rollout stage, prior pin, replay against pre-release traces. |
| Improvement | Operators send feedback in Slack; someone updates the prompt. | Learning is anecdotal, unversioned, and hard to verify. | Corrections become typed StrategyRules or pack changes, then pass replay and release gates before promotion. | FeedbackRecord, StrategyRule proposal, diff, golden replay, approver, promotion record. |
| Multi-agent work | Subagents share whatever context and tools the orchestrator hands them. | Delegation leaks authority. Failures cascade across agents with weak provenance. | Subagent lanes inherit bounded context, scoped authority, parent decision refs, and explicit handoff contracts. | parent_decision_id, lane id, handoff envelope, per-lane budget, tool surface per lane. |
| Security posture | Security reviews the prompt, model provider, and API permissions. | Prompt injection, tool misuse, memory poisoning, and over-privileged credentials cross boundaries. | ContextOS treats every boundary as enforceable: compile, plan, execute, memory write, approval, replay, release. | Threat model mapped to controls, least-privilege manifests, redaction tests, memory review, emergency stop. |
These are target properties of a ContextOS-conformant deployment. The public repository contains a typed contract and a deterministic Context Pack compiler reference, not a production runtime that can demonstrate all these controls end to end. A team must implement the Tool Gateway, policy enforcement, record storage, replay inputs, and release gates—and test that no side-effecting path bypasses them. The harness can reduce unauthorized actions and make failures diagnosable; it cannot guarantee that the model’s judgment is correct or that a downstream provider behaved as expected.
The important shift
The before-state agent is optimized for “can it finish the task?”
The after-state ContextOS agent is optimized for five harder questions:
| Question | Why it matters | ContextOS artifact |
|---|---|---|
| Was this the right task? | Autonomy is unsafe if the runtime cannot name the intent and allowed task. | Intent-Task Catalog, intent_ref, task template |
| Did it see the right context? | A correct model with wrong context still acts incorrectly. | Context Pack, CompiledContext, evidence manifest |
| Was it allowed to act? | Tools change real systems; authorization cannot live in prose. | Tool Gateway, approval-mode tiers, policy decisions |
| Can we prove what happened? | Trust collapses when incident review depends on interpretation. | DecisionRecord, trace, tool transcript, scorecard |
| Can we improve without drift? | Agent quality must improve through release engineering, not folklore. | Feedback Store, StrategyRule, replay, release gate |
Why “just use an agent framework” is not enough
Frameworks help you build. They do not automatically decide your enterprise contract.
| Framework primitive | What it gives you | What ContextOS still has to define |
|---|---|---|
| Agent loop | Calls models and tools until completion. | Which intents deserve an autonomous loop, what budget applies, and when the Critic must stop. |
| Tool calling | Lets the model invoke functions or hosted tools. | Which capabilities are surfaced for this tenant, user, intent, risk class, and pack version. |
| Handoffs | Moves work between specialist agents. | Who owns the final decision, what authority transfers, and how parent and child records link. |
| Guardrails | Blocks or validates selected inputs, outputs, or tool calls. | Which policy bundle is authoritative, where checks run, and how denials become replayable evidence. |
| Tracing | Shows model calls, tool calls, handoffs, and spans. | Which trace fields are mandatory, how trace joins to DecisionRecord, and how replay verifies it. |
| Human review | Pauses sensitive tool calls for approval. | Which evidence is frozen, who may approve, what happens on timeout, and how approval affects audit. |
| Sandbox | Runs code or tools in a constrained environment. | Which sandbox profile is allowed by pack, how outputs are classified, and how attestations are recorded. |
The harness is the layer that turns those primitives into a production contract.
Risk translation table
Agentic AI risks are not abstract. They map directly to missing runtime controls.
| Risk pattern | Before ContextOS symptom | Harness control to test |
|---|---|---|
| Prompt injection | Retrieved text or user input tells the model to ignore policy. | Context is treated as evidence, not authority; policy runs outside the model; Tool Gateway re-validates every call. |
| Excessive agency | The agent has access to tools that are unrelated to the request. | Compiled tool manifest exposes only capabilities allowed by pack, policy, tenant, safety mode, and delegation. |
| Tool misuse | The model calls the right tool with unsafe arguments. | Arg constraints, policy decisions, idempotency keys, native ActionRisk checks, the v1 approval-mode projection, and Critic verification before execute. |
| Sensitive data leakage | Tool output or memory recall enters a response without classification. | Data classification, redaction rules, promotion-aware memory, output guardrails, and trace-linked evidence refs. |
| Memory poisoning | A malicious conversation creates durable future behavior. | Capture-only raw memory, promotion review, contradiction checks, consent basis, decay, and rollbackable memory refs. |
| Cascading failure | One bad intermediate step causes many downstream actions. | Bounded Planner / Executor / Critic loop, max replan attempts, tool-call caps, failure playbooks, and rollback. |
| Invisible drift | A model or policy update changes behavior with no obvious code diff. | Release tuple pinning, golden replay, evaluator scorecards, and decision-record comparison. |
| Audit tampering | Logs can be edited, incomplete, or impossible to join. | Require trace-linked DecisionRecords and replay inputs; use append-only storage and hash chaining when the deployment adopts that audit profile. |
What changes in one run
Consider a refund request for order ord_881 worth INR 4,200. The table is a design example, not a report of a deployed ContextOS runtime. Its difference is clearest at the points where the agent might be wrong or an external tool might be uncertain.
| Stage | Before: agent demo | After: ContextOS-governed run |
|---|---|---|
| Request | ”Refund order ord_881 for INR 4200” enters the support prompt. | The invokeAgent request names the tenant, user delegation, agent workload identity, pinned pack refs, canonical intent, and trace. The runtime derives a RunContext and its safety ceiling. |
| Context | Agent searches docs and customer history. | Compiler builds CompiledContext from ctxpack.support@version, pinned KG snapshot, policy bundle, evidence manifest, and budget report. |
| Plan | Model says it will look up the order and issue refund. | Planner proposes steps; Critic checks tool allow-list, required evidence, approval mode, and argument bounds. |
| Read tool | Order lookup runs. | Tool Gateway executes adp_orders.lookup as read_only, emits toolResult with evidence ref and trace span. |
| Policy | Prompt says high-value refunds need approval. | A versioned policy decision evaluates amount, eligibility, delegation, and the required gate. If evidence is missing or policy denies the request, the write stops here. |
| Approval | Agent asks a human in UI. | If policy requires a gate, the approval request binds approver identity to a frozen evidence snapshot. Rejection or timeout leaves the write blocked and produces a reviewable outcome. |
| Write tool | Payment API is called. | Only after the gate and argument checks pass does the Tool Gateway submit the refund with an idempotency key and scoped authority. A timeout is unresolved until a provider receipt or lookup confirms whether a mutation occurred. |
| Final answer | Agent writes “refund issued.” | The customer-facing answer reflects the observed tool outcome. A DecisionRecord links evidence, policy decisions, approvals, controls, budget usage, lineage, and trace; scorecard and audit hash depend on the decision profile. |
| Later audit | Engineer searches logs. | An auditor uses the trace and record to fetch pinned inputs and tool transcripts. Replay compares deterministic artifacts exactly and model-dependent behavior against declared checks, without issuing another refund. |
Three outcomes are worth testing before release: an eligible refund proceeds only with the required approval; an ineligible refund is rejected before a write; an ambiguous payment timeout remains unresolved until reconciliation finds the provider outcome. The useful metric is not merely “refund completed.” It is unauthorized refunds prevented, eligible refunds completed, and uncertain mutations reconciled—each with the evidence needed to explain the result.
Sample prompts vs governed prompts
ContextOS keeps the prompt as an instruction for the model. The prompt does not grant tool authority or define the authoritative policy boundary; the run and tool contracts do that.
| Use case | Bare LLM prompt | Prompt plus tools | Prompt wrapped with ContextOS constructs | Why the third version is different |
|---|---|---|---|---|
| Customer refund | ”You are a support agent. Decide whether to refund this order and respond politely." | "You can call lookup_order and issue_refund. Follow refund policy. Ask for approval when needed.” | Pinned ctxpack.support@5.2.0, canonical support.refund intent, a runtime RunContext, a refund DecisionSpec, and a compiled manifest with read and gated write capabilities. | The model can propose, but policy, approval, amount bounds, evidence, and idempotency are checked outside the prompt. |
| Regulated back office | ”Review this exception and decide whether it can be approved." | "Use the policy docs and case tools. Escalate risky cases.” | Tenant and intent in RunContext, a versioned policy bundle, required evidence, an approval gate, and DecisionRecord statuses such as DECIDED, REJECTED, ESCALATED, or DEFERRED. | The decision becomes comparable across reviewers because each outcome cites a declared evidence contract and policy version. |
| Incident command | ”Triage this incident and recommend next steps." | "Use logs, metrics, and runbook tools. Page owners if needed.” | ContextPack(incident.command) pins runbooks, service graph, SLOs, escalation matrix, and allowed tools; Tool Gateway gates paging, rollback, and traffic-shift actions. | The agent can help coordinate, but high-blast-radius actions still require explicit controls, owner identity, and replayable evidence. |
| Software delivery | ”Review this PR and merge it if tests look good." | "Use GitHub, CI, and code search tools. Comment on problems.” | A PR-merge DecisionSpec declares required evidence: diff summary, tests, static checks, owner approval, risk classification, and rollback note. | Merge authority depends on a typed decision with test evidence, approval provenance, and release-gate status. |
| Data stewardship | ”Fix this data quality issue." | "Query the warehouse and update records if confidence is high.” | ContextOS binds ontology version, CEID namespaces, data classification, lineage graph, write capability, and remediation DecisionRecord. | The system knows which entity is being changed, which source is authoritative, and whether the write is allowed for that data class. |
The prompt should get smaller as the harness gets stronger.
| Layer | Belongs in prompt | Belongs in ContextOS contract |
|---|---|---|
| Tone | ”Be concise, neutral, and explain next steps.” | Customer communication templates and redaction rules. |
| Task shape | ”Evaluate refund eligibility and explain the result.” | Intent, task template, DecisionSpec, required evidence, allowed outcomes. |
| Tool choice | ”Look up the order before deciding.” | Compiled tool manifest, capability constraints, native ActionRisk, v1 compatibility projection, idempotency policy. |
| Policy | ”Do not violate refund policy.” | Versioned policy bundle, JsonLogic rules, priority, policy_decision_id, release gate. |
| Safety | ”Escalate risky cases.” | must_escalate, approval gates, risk class, evaluator thresholds, failure playbooks. |
| Audit | ”Mention why you decided.” | DecisionRecord with evidence refs, approvals, controls, lineage, scorecard, trace, hash. |
The objects belong at different boundaries. This is a contract sketch, not a JSON request you can send to an API:
| Boundary | Refund example | Control it owns |
|---|---|---|
| Request | invokeAgent carries request_id, tenant, user delegation, agent workload identity, context_pack_refs, input intent, budget hints, and trace. | Names the principal, task, pinned inputs, and trace before planning begins. |
| Runtime context | RunContext adds run_id, safety_mode, and the materialized run_budget. | Sets the run’s authority ceiling and resource limits. |
| Compilation | CompiledContext resolves the pinned pack, policy bundle, evidence requirements, and tool manifest. | Limits what context and capabilities the model can use. |
| Tool call | ToolCallEnvelope carries capability, arguments, approval-mode compatibility fields, policy decision, evidence refs, and idempotency key. | Re-checks authority and arguments immediately before an external effect. |
| Receipt | DecisionRecord links the outcome to policy decisions, approvals, evidence, controls, budget usage, lineage, and trace. | Makes the decision reviewable; optional audit and replay fields attach when their profiles apply. |
For the field-level request example, use the canonical invokeAgent envelope. Keeping these objects separate matters: a compiled tool manifest is a compiler output, not a property the caller can assert in a request.
Adoption path
Do not try to build the whole control plane in one sprint. Ship the smallest load-bearing slice.
| Step | Build this first | Done when |
|---|---|---|
| 1. Name the run | RunContext plus canonical trace_id on every invocation. | Every agent call has tenant, user, intent, safety mode, budget, and trace. |
| 2. Compile context | One Context Pack for one workflow. | The model sees a bounded context envelope, not an ad-hoc prompt construction. |
| 3. Gate tools | Tool Gateway for one read tool and one side-effecting tool. | No tool call bypasses schema validation, policy, identity, idempotency, and trace. |
| 4. Emit records | DecisionRecord for the primary decision. | Every successful, rejected, escalated, or deferred run has a durable receipt. |
| 5. Replay one case | Offline replay for one normal run and one denied or uncertain boundary run. | Deterministic outputs compare exactly; model-dependent stages meet declared property or scorecard checks without executing live side-effecting tools. |
| 6. Score releases | Policy / Utility / Latency / Safety / Economics scorecard. | A prompt, pack, policy, model, or tool change cannot promote without a verdict. |
| 7. Close improvement | Operator correction -> StrategyRule or pack proposal -> replay -> approval. | A measured correction becomes a versioned release candidate. |
Design review questions
Use this table before letting an agent act on anything important.
| Ask this | Good answer | Bad answer |
|---|---|---|
| What is the maximum approval mode this run can reach? | Declared in RunContext.safety_mode, tool manifests, policy bundle, and DecisionSpec. | ”The prompt tells it to ask first.” |
| Which tools were visible to the model? | A compiled tool manifest for the intent and tenant. | ”It had access to our internal tool server.” |
| What evidence supports the final action? | evidence_refs[] on the DecisionRecord, with source, hash, snapshot, and timestamp. | ”It saw the customer record.” |
| How do we know policy ran? | policy_decisions[] with bundle version, rule ids, inputs, and verdict. | ”The model was instructed with policy.” |
| Can we reproduce this tomorrow? | Replay packet pins available inputs and transcripts; exact checks cover deterministic stages and declared checks cover model-dependent stages. | ”We can rerun the request.” |
| What happens if the agent loops? | RunBudget, max tool calls, max replans, no-progress detection, and failure playbook. | ”The model usually stops.” |
| How does a correction become durable? | FeedbackRecord -> StrategyRule or pack diff -> golden replay -> release gate. | ”We will update the prompt.” |
What ContextOS is not
| Misread | Correct interpretation |
|---|---|
| ”ContextOS replaces agent frameworks.” | No. It defines the contract around any framework: context, authority, records, replay, evaluation, and release. |
| ”Harness engineering slows teams down.” | It adds real compile, policy, approval, and recording work. Reusable controls may repay that cost across workflows; measure latency, cost, and avoided incidents rather than assume a speedup. |
| ”This is only for regulated industries.” | Any workflow with customer state, money, production data, code changes, or durable memory needs these controls. Regulation only makes the need obvious. |
| ”Observability is enough.” | Traces show execution. DecisionRecords bind the governed outcome to evidence and policy. Replay checks reproducible parts of that outcome. |
| ”Better models will make this unnecessary.” | Better models increase the surface area worth automating. More useful autonomy raises the value of boundaries, not lowers it. |
The one-line version
Before a governed contract, an agent may complete a task while leaving context, authority, and outcome evidence scattered across prompts and logs.
With a ContextOS-conformant harness, the same task has pinned context, scoped tool authority, policy checks, a DecisionRecord, and a replayable evidence path. Evaluation and release gates determine which changes can gain more authority.
That is a testable difference between a successful demo and a workflow an organization can review, limit, and improve.